AWS Glue and Athena: ETL and SQL on S3 Data Lakes Explained
Data lakes on S3 fill with CSV and Parquet. Someone still needs to clean columns and let analysts write SQL without a big cluster on day one. AWS Glue catalogs and transforms; Amazon Athena runs SQL directly on S3. Together they are the broom and the notebook for your lake.
What you'll learn in this chapter
- Why lakes need a catalog
- Glue crawlers, jobs, Data Catalog
- Athena SQL, workgroups, cost control
- Partitions and file formats
- Lab, errors, FAQ, interview
1. Everyday example first
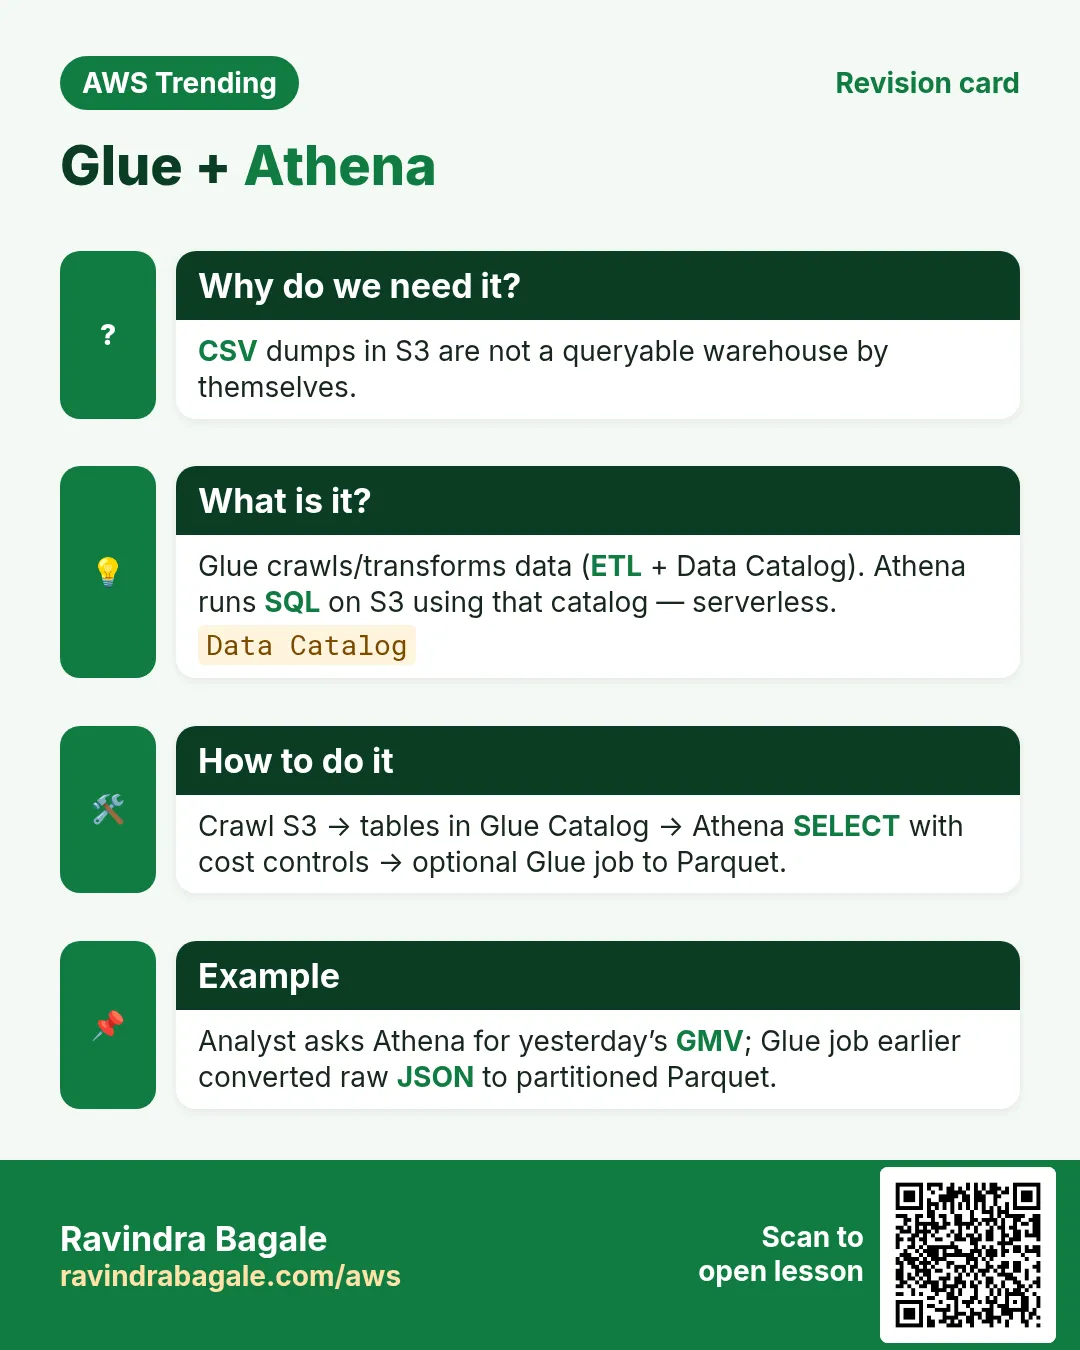
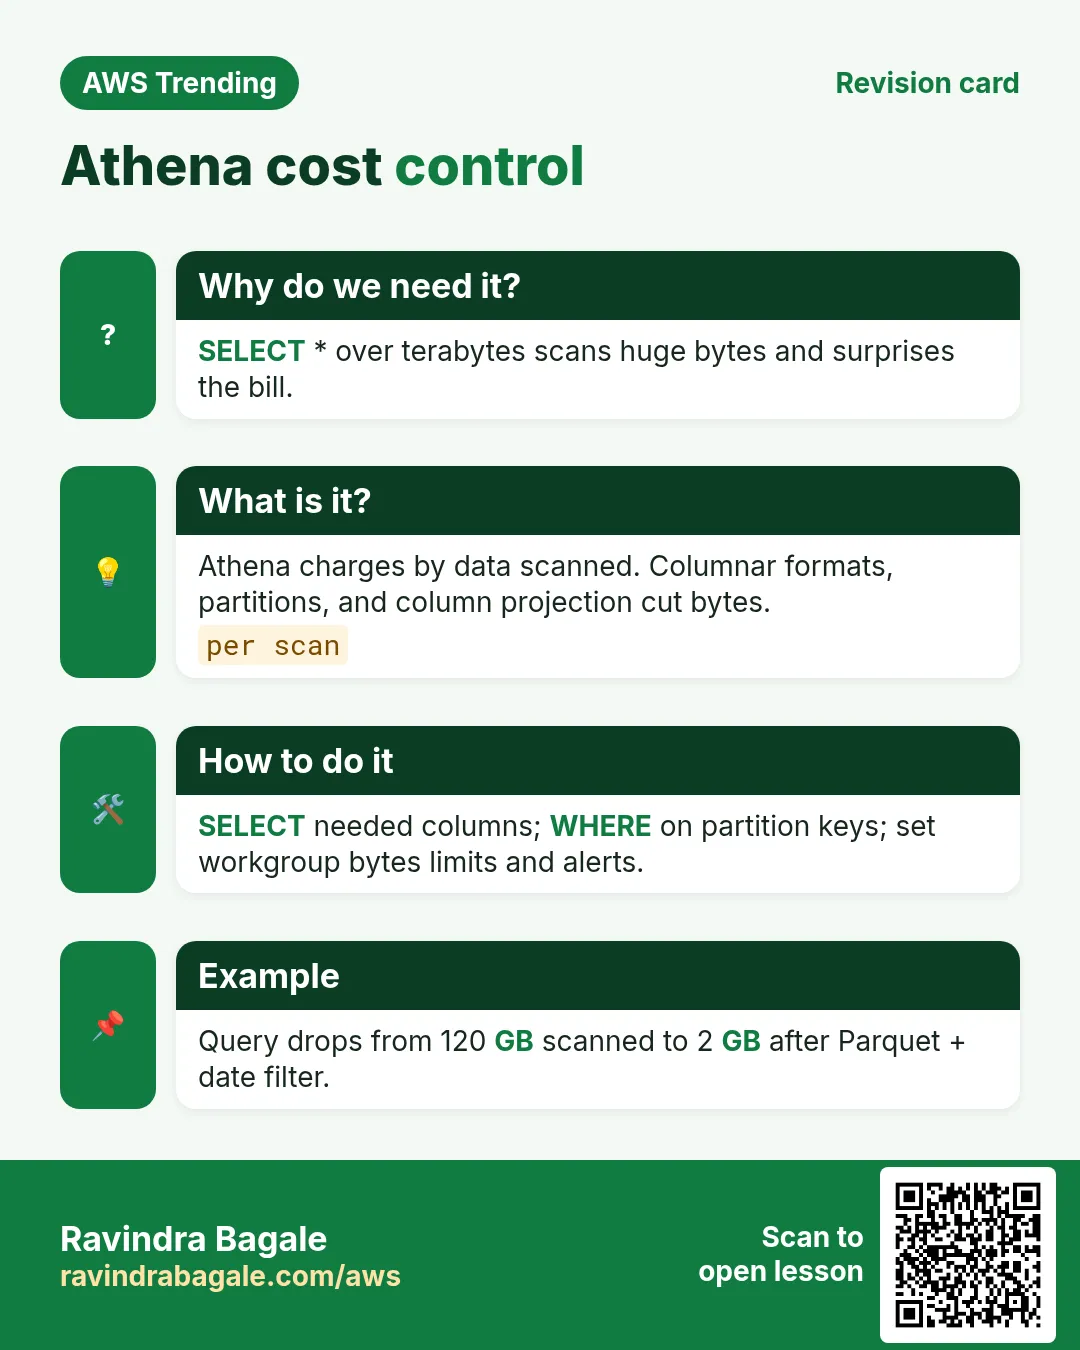
A retail chain drops daily sales Parquet into s3://company-lake/sales/date=... Glue crawler updates the table. A business analyst runs Athena: SELECT store, sum(amount) ... WHERE date=... and pays per data scanned — so partitions matter.
2. Why Glue + Athena?
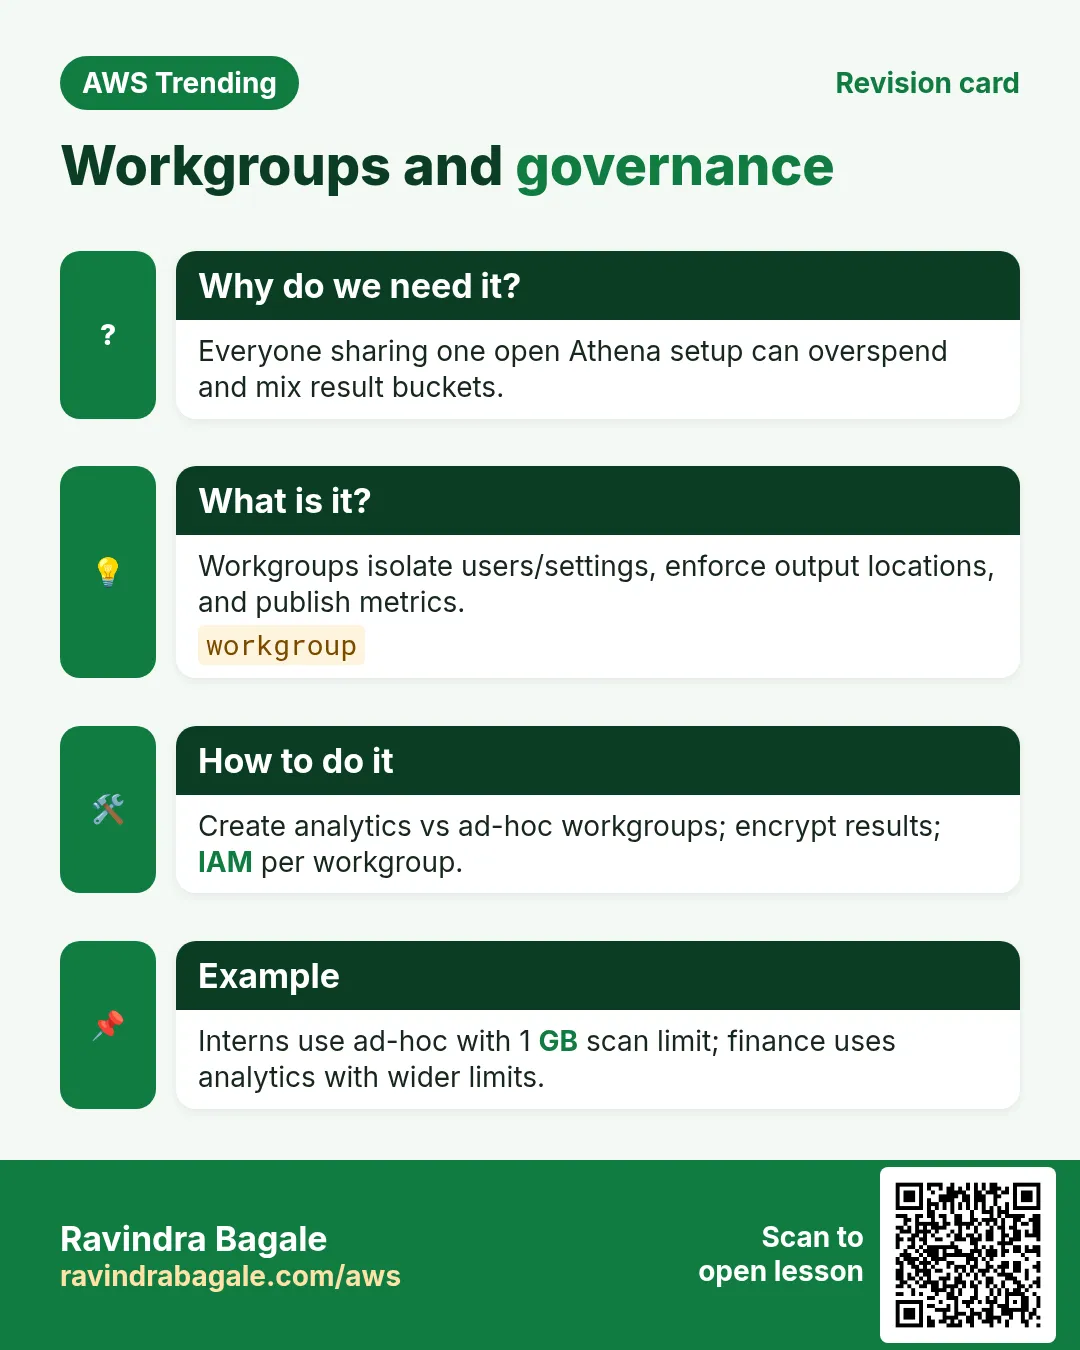
Why do we need this?
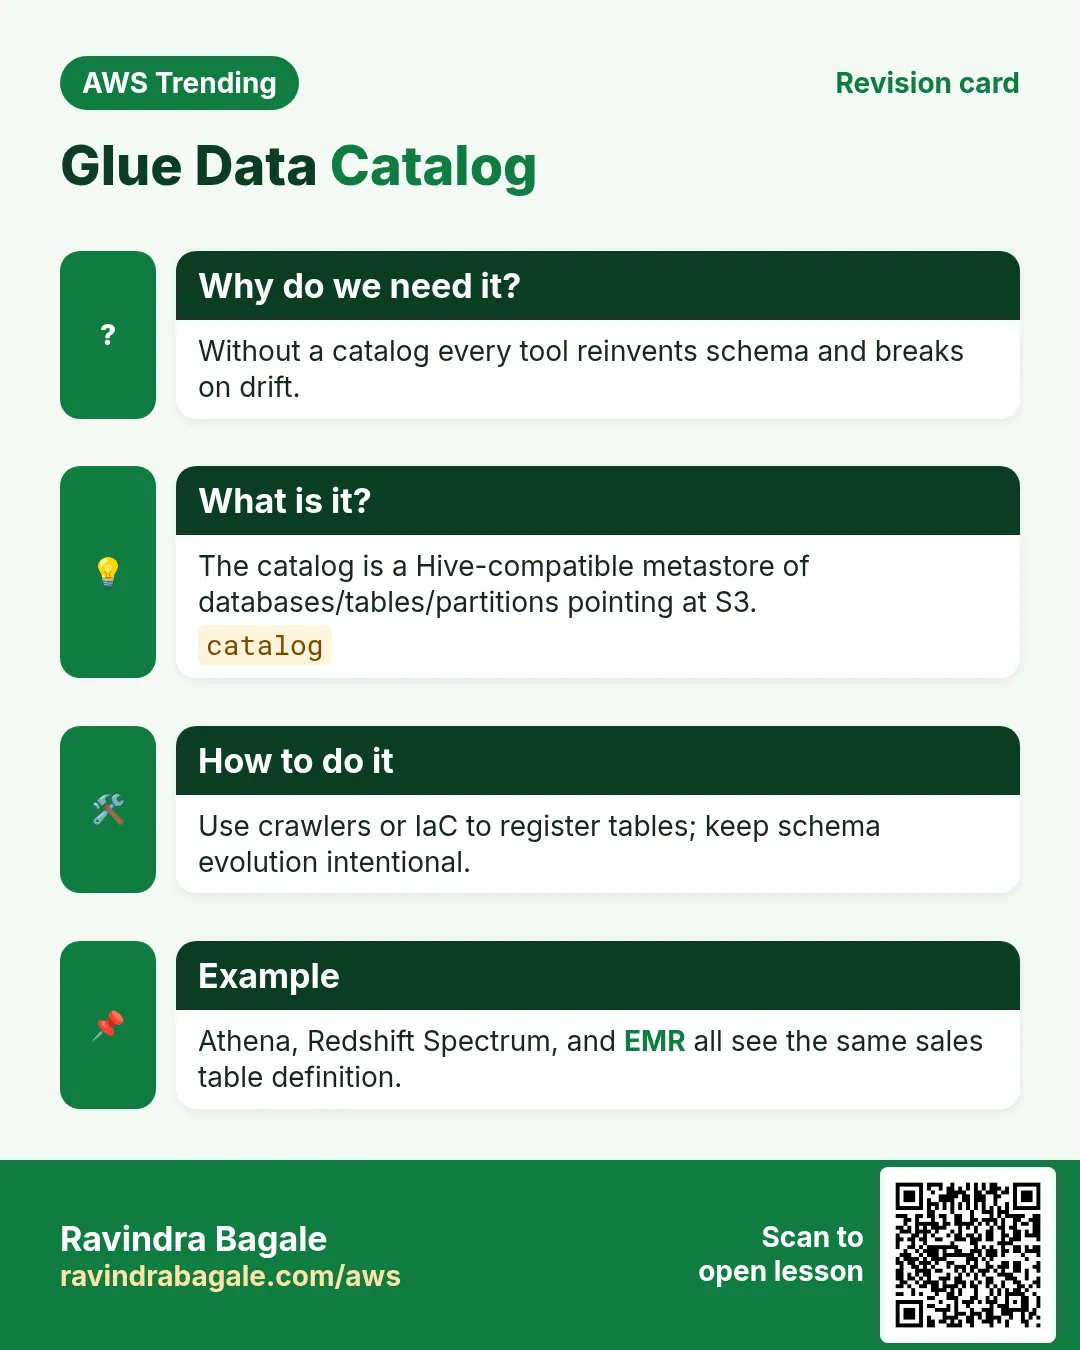
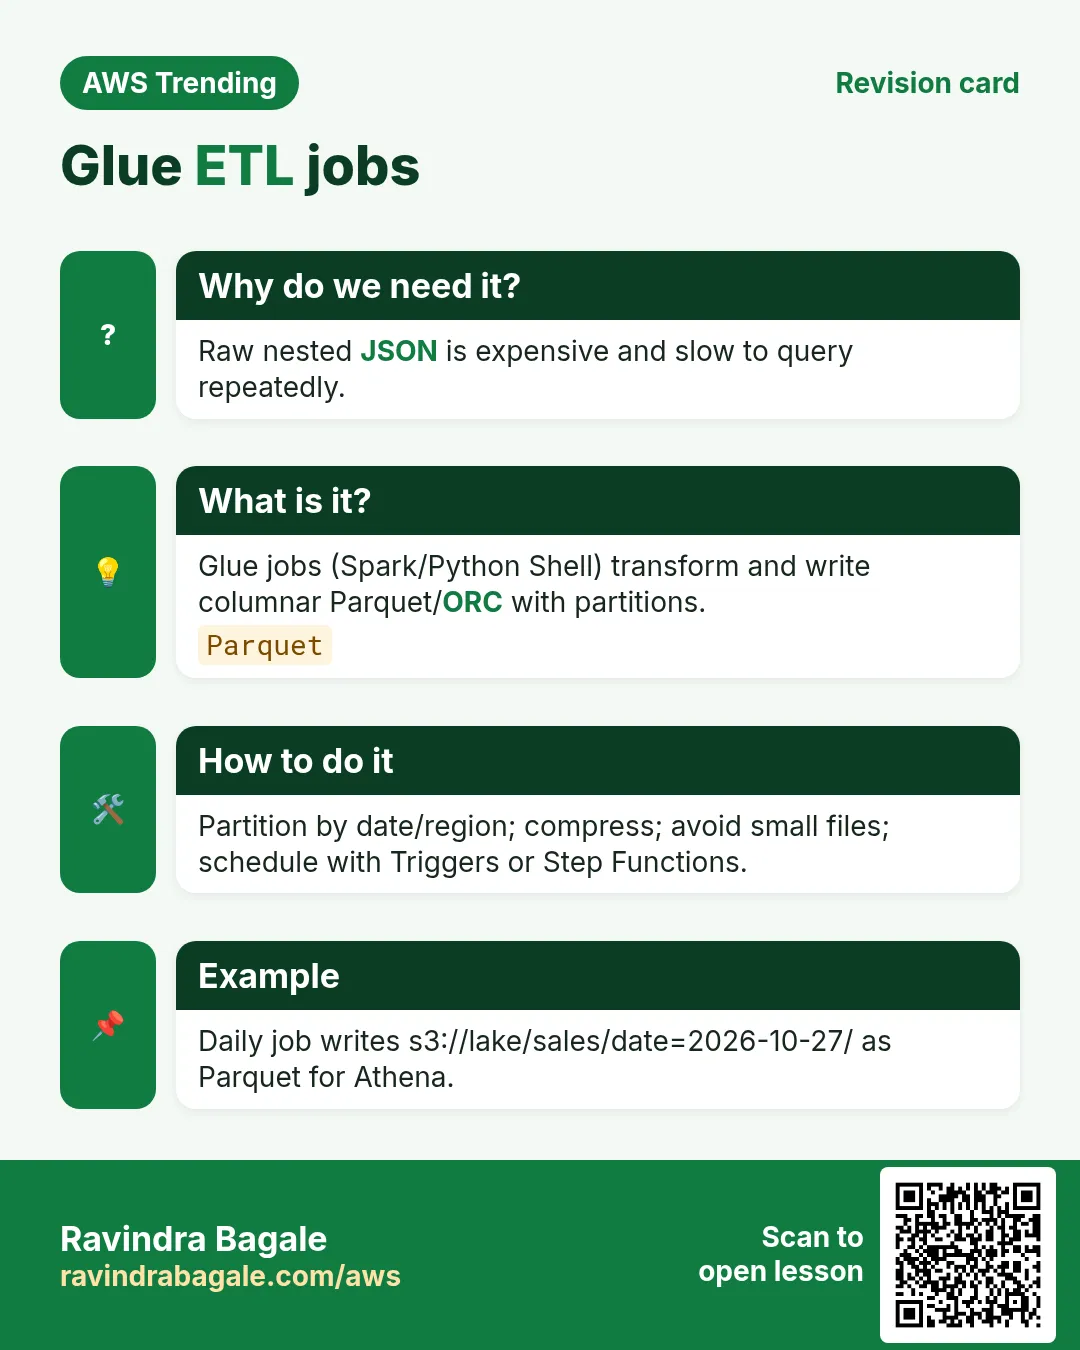
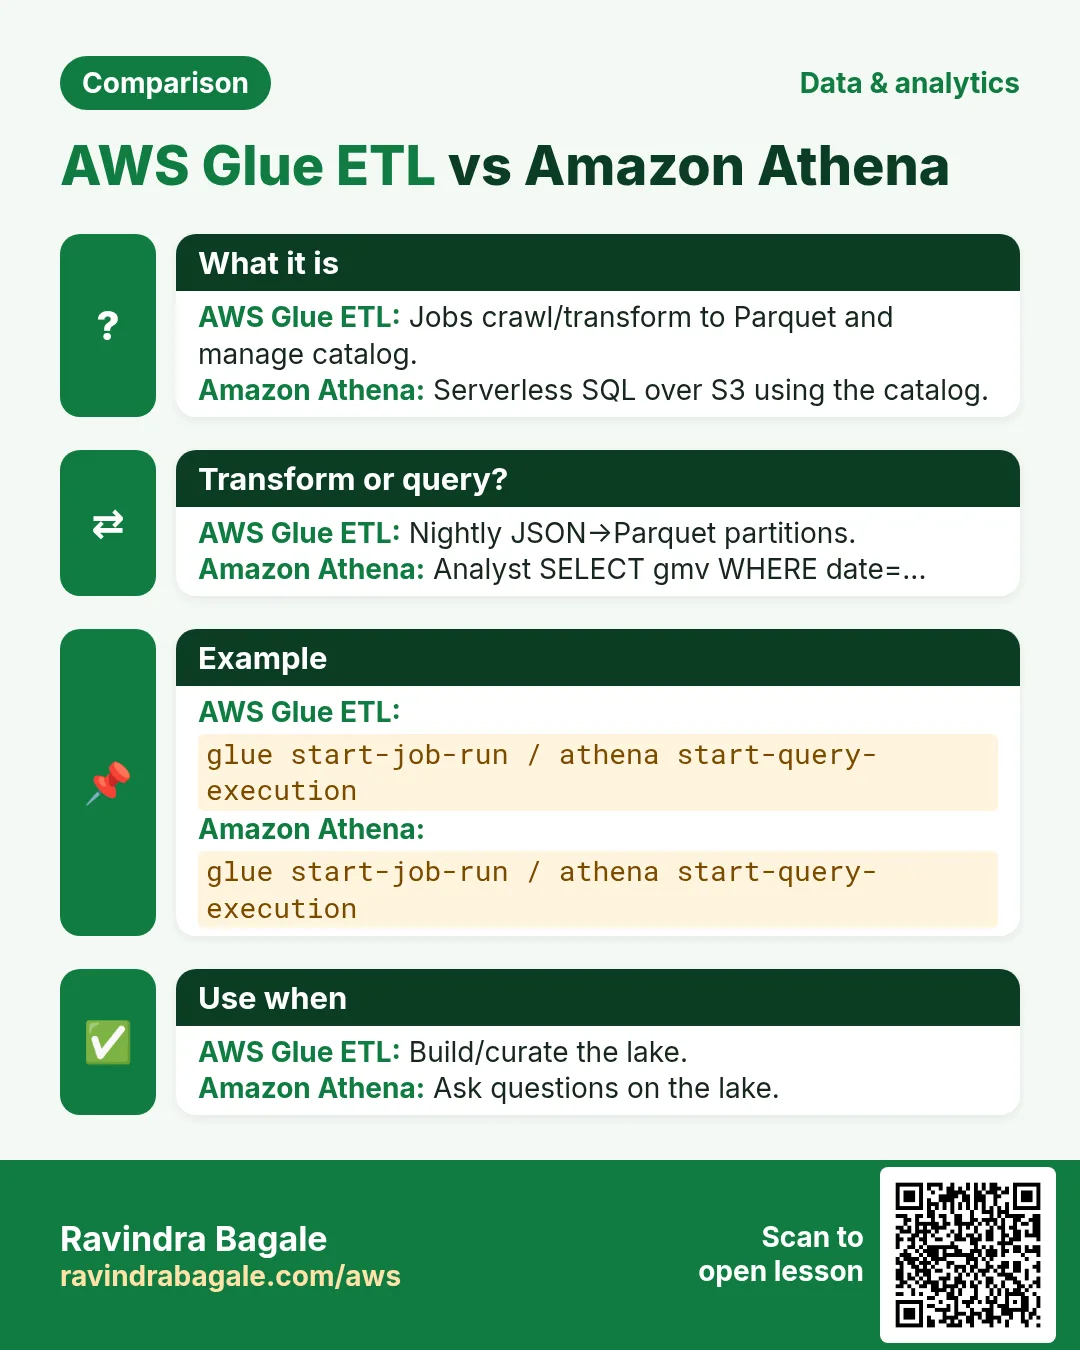
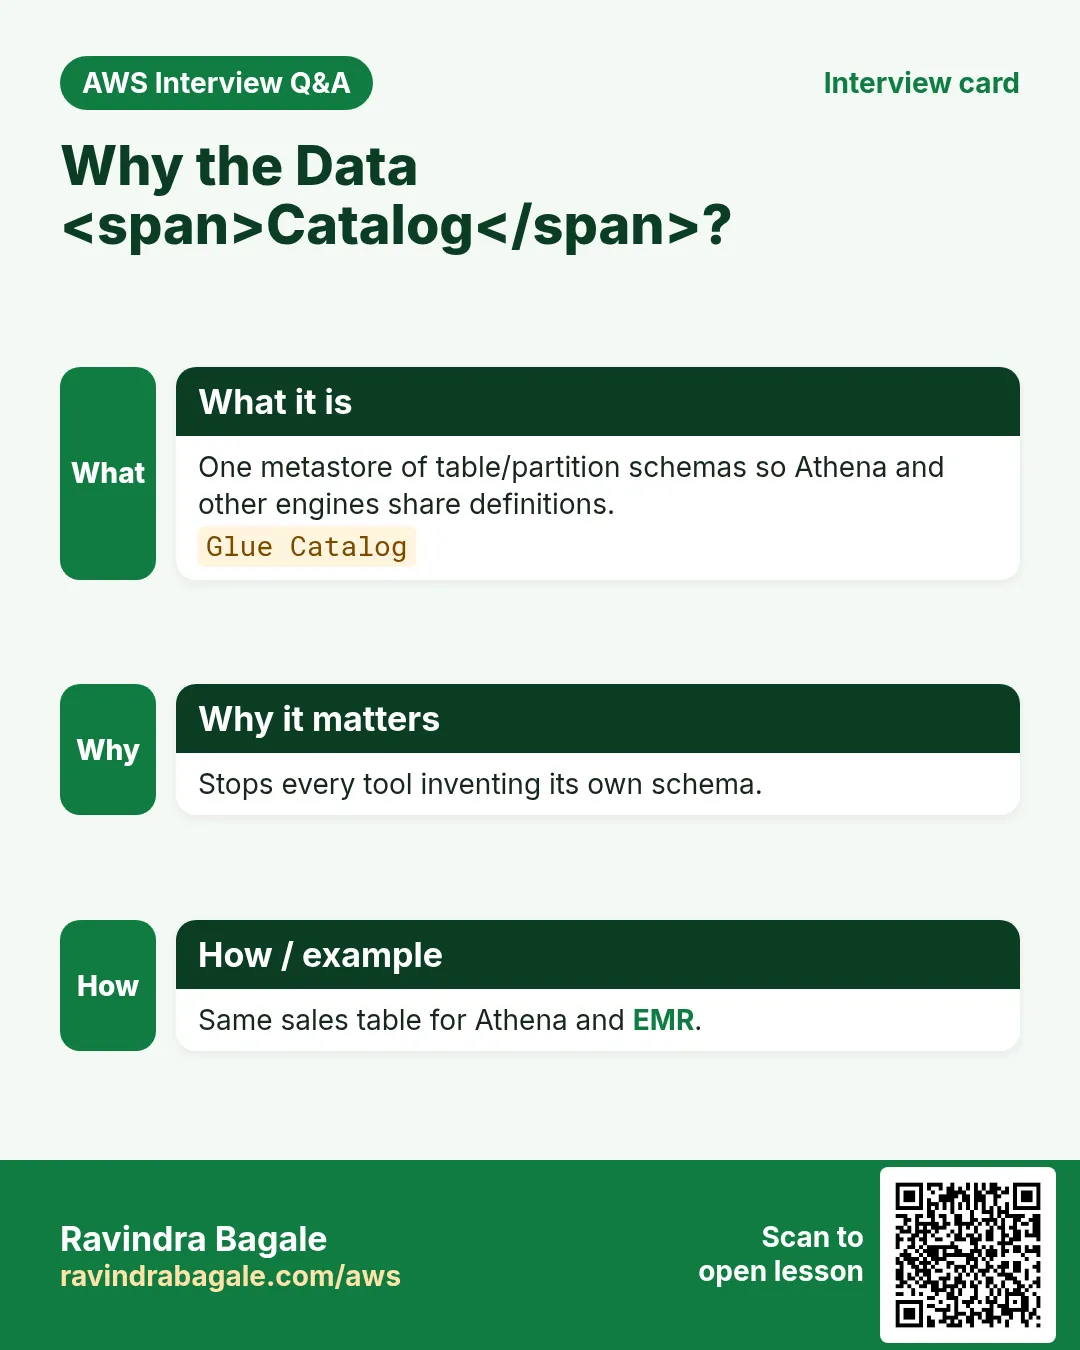
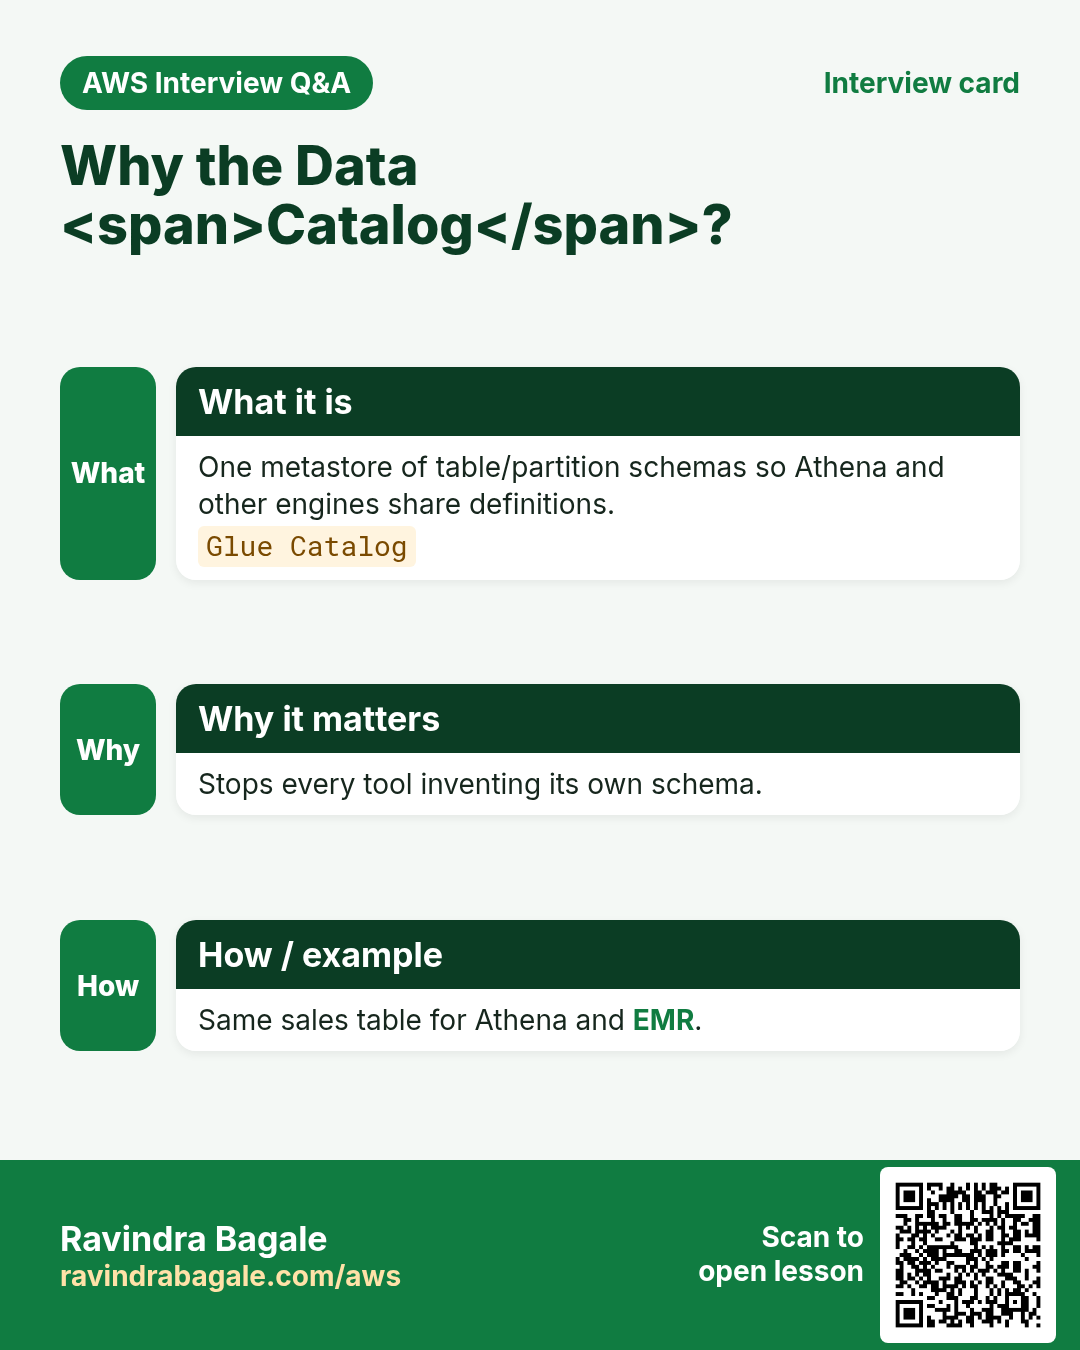
Without a catalog, every job hard-codes paths. Without serverless SQL, analysts wait for warehouses. Glue Data Catalog is the hive-style metastore; Athena queries it. Glue ETL (Spark) cleans heavy jobs when SQL alone is not enough.
3. What each piece does
What is it?
| Piece | Job |
|---|---|
| Data Catalog | Databases/tables/schemas over S3 |
| Crawler | Infer schema from files |
| Glue Job | ETL with Spark/Ray etc. |
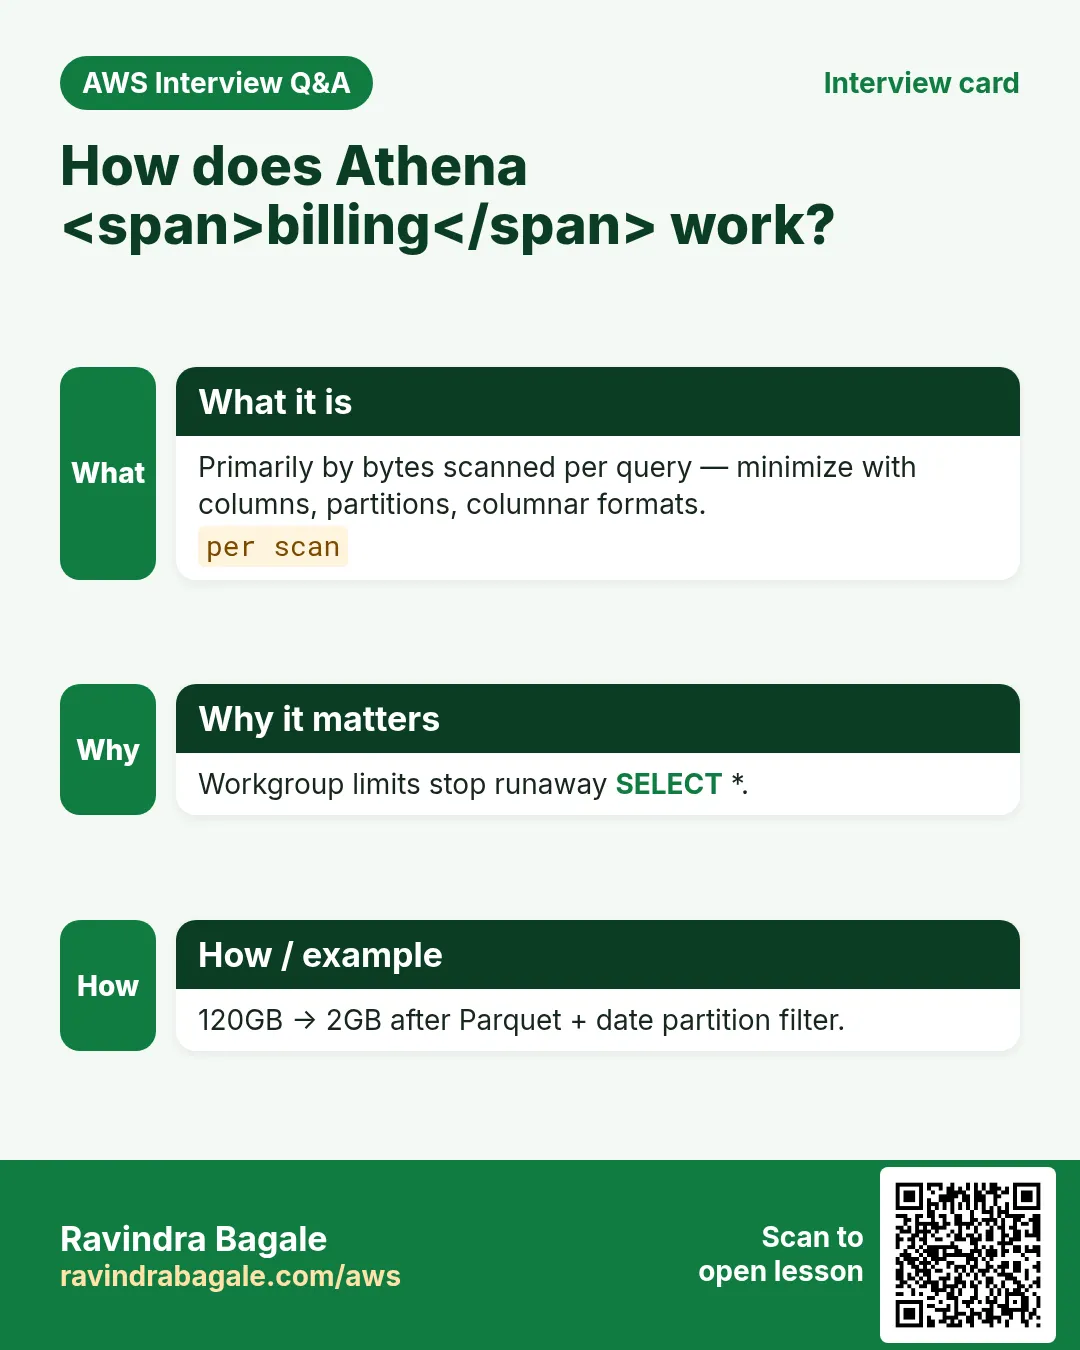
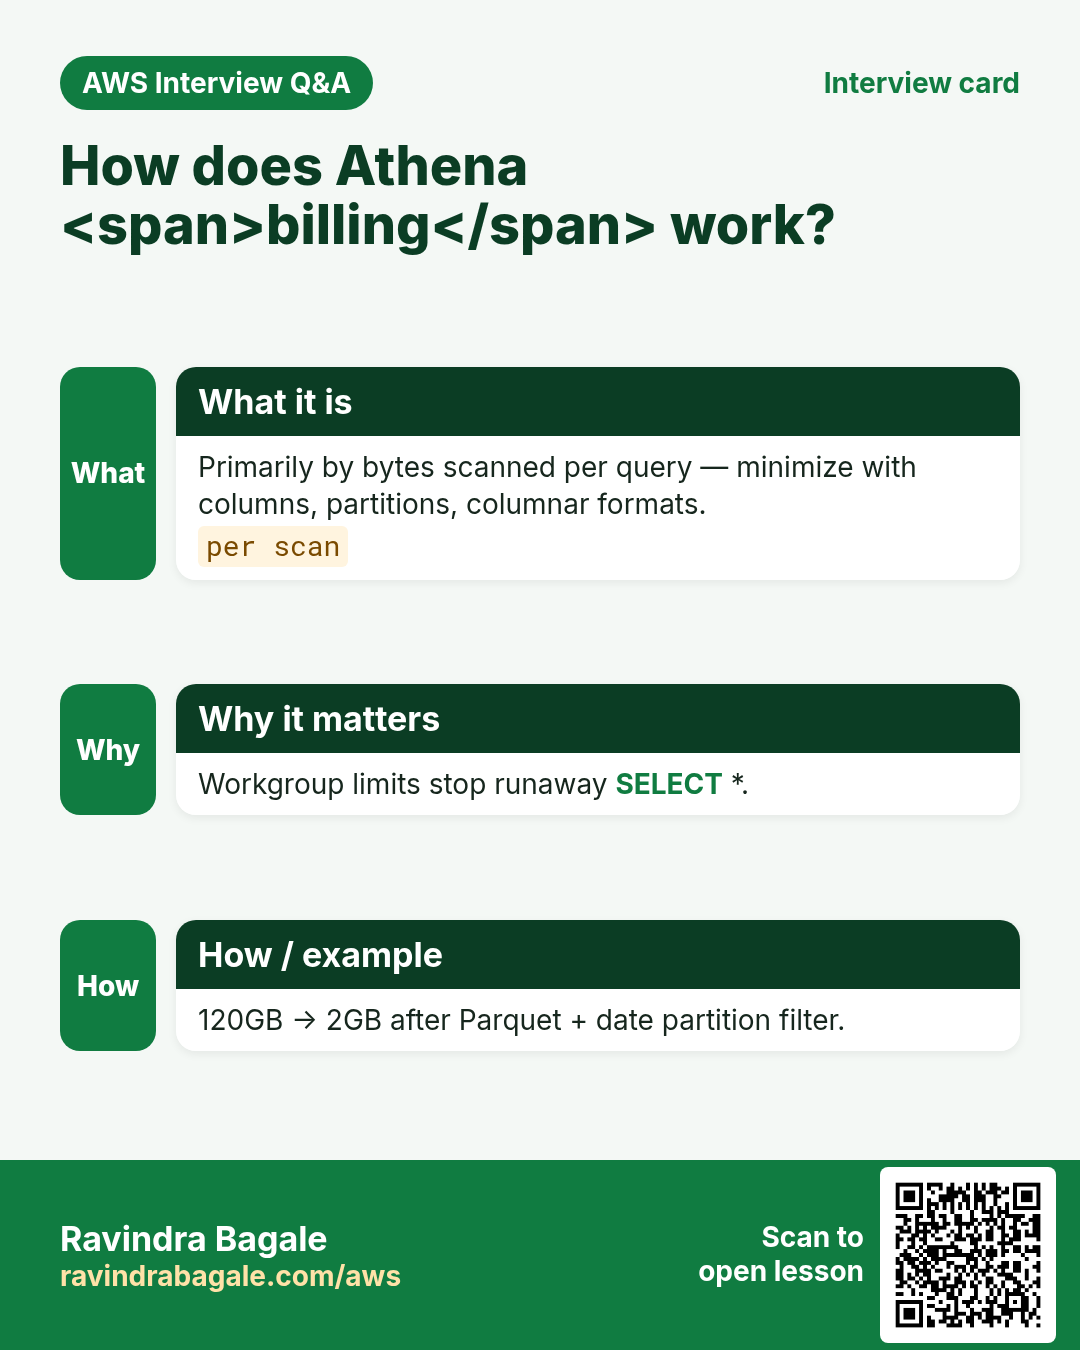
| Athena | SQL on catalog tables; pay per scan |
4. How to keep costs sane
How to do it (step by step)
- Store columnar Parquet/ORC, not giant CSV.
- Partition by date (and careful other keys).
- Use Athena workgroups with bytes-scanned limits.
- SELECT only needed columns.
- Compress; avoid small-file explosions.
- Lifecycle raw junk out of hot prefixes.
-- Athena mental model
-- SELECT store_id, SUM(amount) AS sales
-- FROM sales
-- WHERE date = '2026-10-27'
-- GROUP BY 1;
-- Partition column in WHERE → less data scanned
5. Industries
- Retail: daily sales lakes
- Adtech: click logs to Parquet
- Healthcare analytics on de-identified exports
- Finance: reconciliations on landed files
6. Lab: query sample with Athena (or paper SQL)
Do this in ap-south-1 (Mumbai) unless your org forbids it. Set a budget alert first.
How to do it (step by step)
- Create/choose an S3 prefix with a tiny CSV/Parquet sample.
- Run a Glue crawler or manual catalog table.
- Open Athena, select workgroup, run COUNT(*).
- Rerun with partition filter; compare data scanned.
- Note IAM: athena, glue, s3 list/get.
Cleanup (stop billing)
- Drop lab databases/tables; empty lab prefixes.
- Disable crawlers on schedule.
7. Common errors and fixes
Each row is a real mistake students and juniors hit. Read the fix before you panic.
| Error / symptom | Fix |
|---|---|
| CSV everything — huge Athena bills | Convert to Parquet. |
| Forgot partition in WHERE | Always filter partitions. |
| Crawler overwrote careful schema | Lock schema; use versioning. |
| Small files millions | Compact with Glue job. |
| Open workgroup no limits | Set per-query scan caps. |
| Public S3 lake | Block public; bucket policies. |
| Glue job IAM * | Scope to lab buckets. |
| JSON nested chaos | Flatten in ETL; document schema. |
| Athena result bucket world-readable | Private results bucket. |
| Timezone partition mistakes | Store UTC; document. |
8. Troubleshooting checklist
- ZERO RECORDS → path/partition mismatch.
- AccessDenied → glue:GetTable + s3:GetObject.
- HIVE_CANNOT_OPEN_SPLIT → bad files/compression.
- Crawler no-op → classify check / exclusions.
- Slow Glue → DPUs / worker type.
- Unexpected cost → workgroup metrics.
9. FAQ
Q. Athena vs Redshift?
Athena=serverless SQL on S3; Redshift=warehouse cluster/serverless warehouse.
Q. Is Glue only Spark?
Spark common; also other engines/options over time — check current.
Q. Do I need crawlers always?
No — IaC/manual tables fine.
Q. Iceberg/ACID?
Modern table formats supported in evolving ways — verify for your region.
Q. Charge when query fails?
Failed queries can still scan — limits help.
10. Interview Q&A
Q. What is the Glue Data Catalog?
Central metastore of databases/tables for analytics.
Q. How Athena prices?
Primarily by bytes scanned per query.
Q. Why Parquet?
Columnar; reads fewer bytes for analytical SQL.
Q. What does a crawler do?
Infers schema and creates/updates tables.
Q. Partition projection?
Athena feature to avoid millions of partition objects — advanced.
Q. Lake vs warehouse?
Lake stores varied files; warehouse optimized curated schemas.
11. Tips in English, Marathi and Hindi
Ravindra Bagale's Tip (EN)
Partitions are a cost feature, not decoration. Put date filters in every habit query.
Ravindra Bagale's Tip (MR)
Partitions = cost feature. प्रत्येक query मध्ये date filter सवय.
Tip (HI)
Partitions सजावट नहीं — cost feature है; हर query में date filter डालो।
Try at home
- Write two Athena queries: bad (full scan) vs good (partitioned).
- Convert a tiny CSV to Parquet with a local tool or Glue idea.
- List IAM actions Athena needs on S3 + Glue.
In short
- Glue catalogs and ETL; Athena SQL on S3.
- Parquet + partitions control cost.
- Workgroups limit surprise bills.
- Secure the lake: no public buckets.
Revision, interview and comparison cards
Revise this lesson in a few minutes. Save the cards on your phone or download them as PNG files. The QR code on each card opens this lesson.
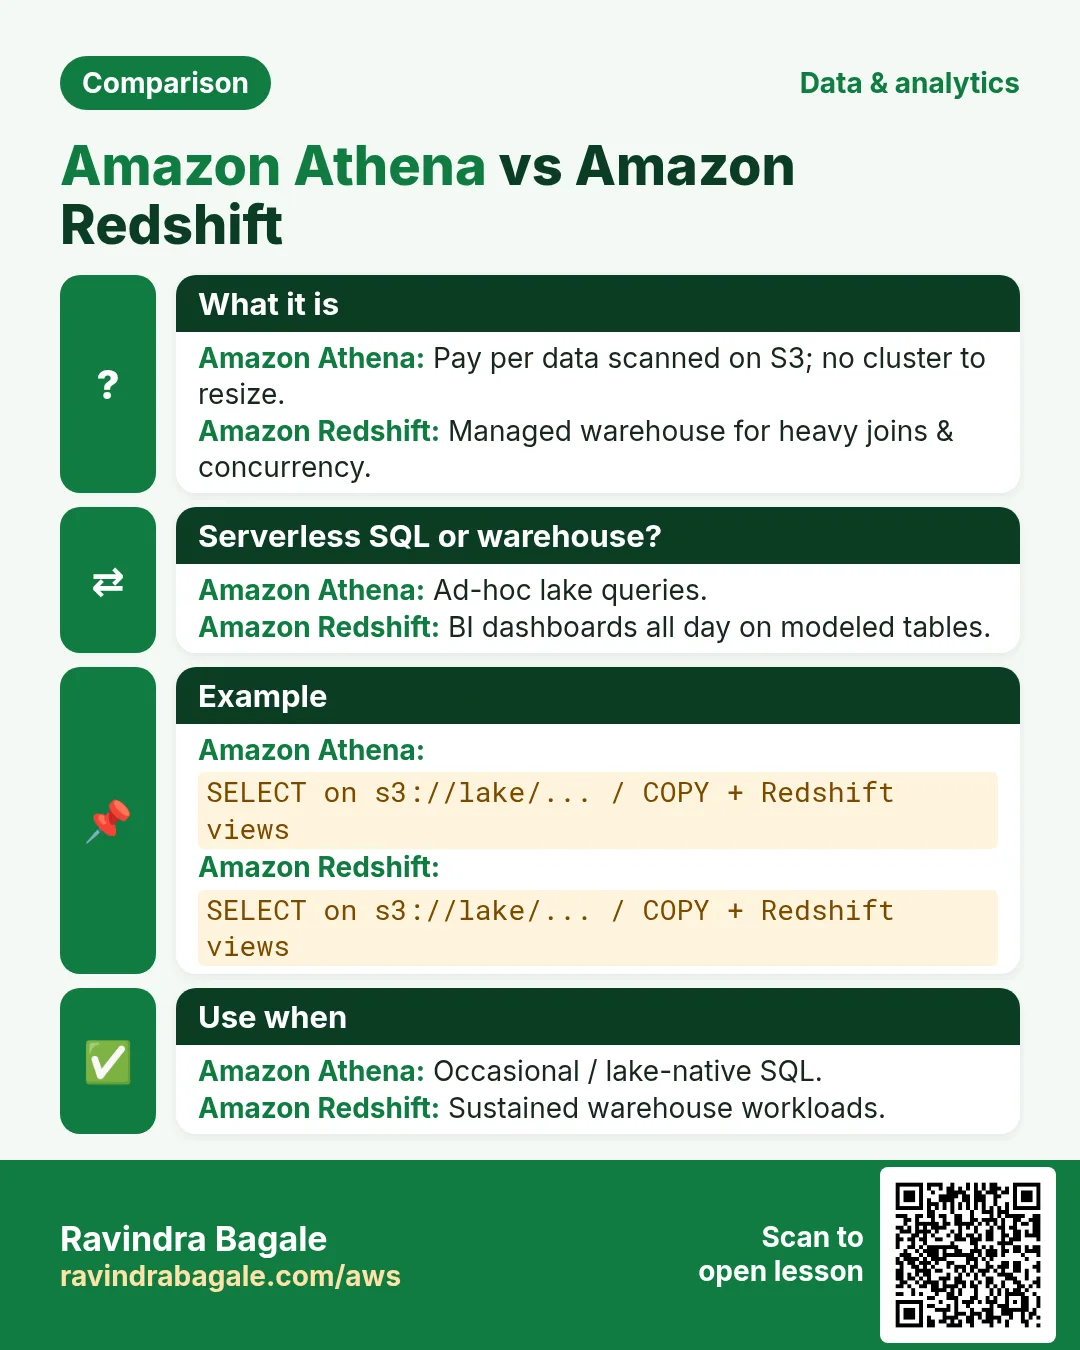
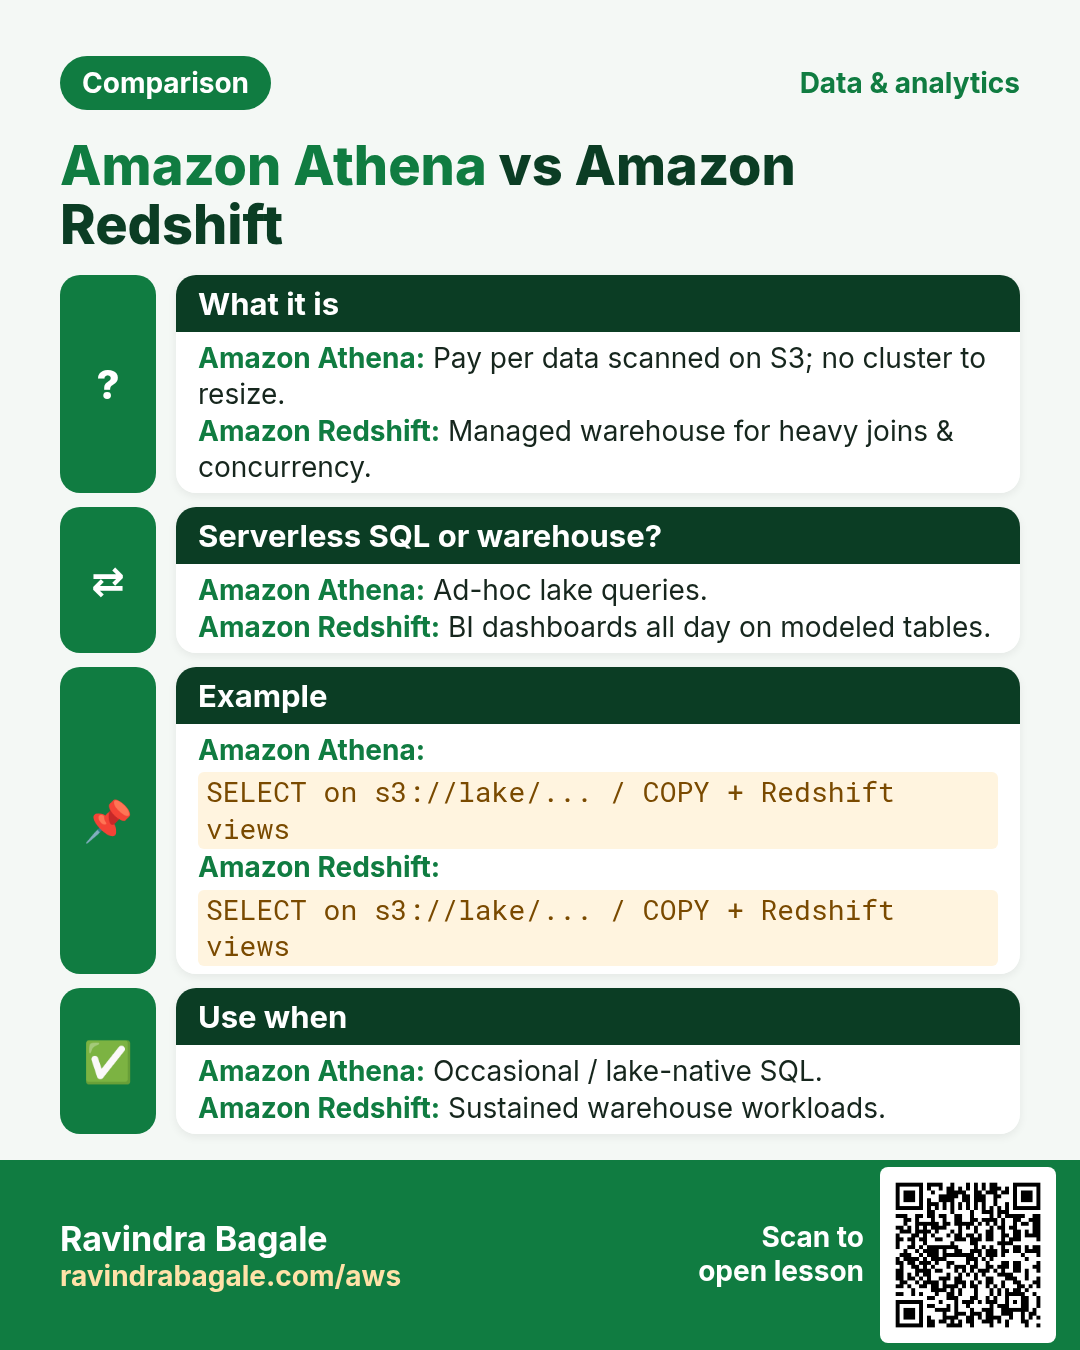
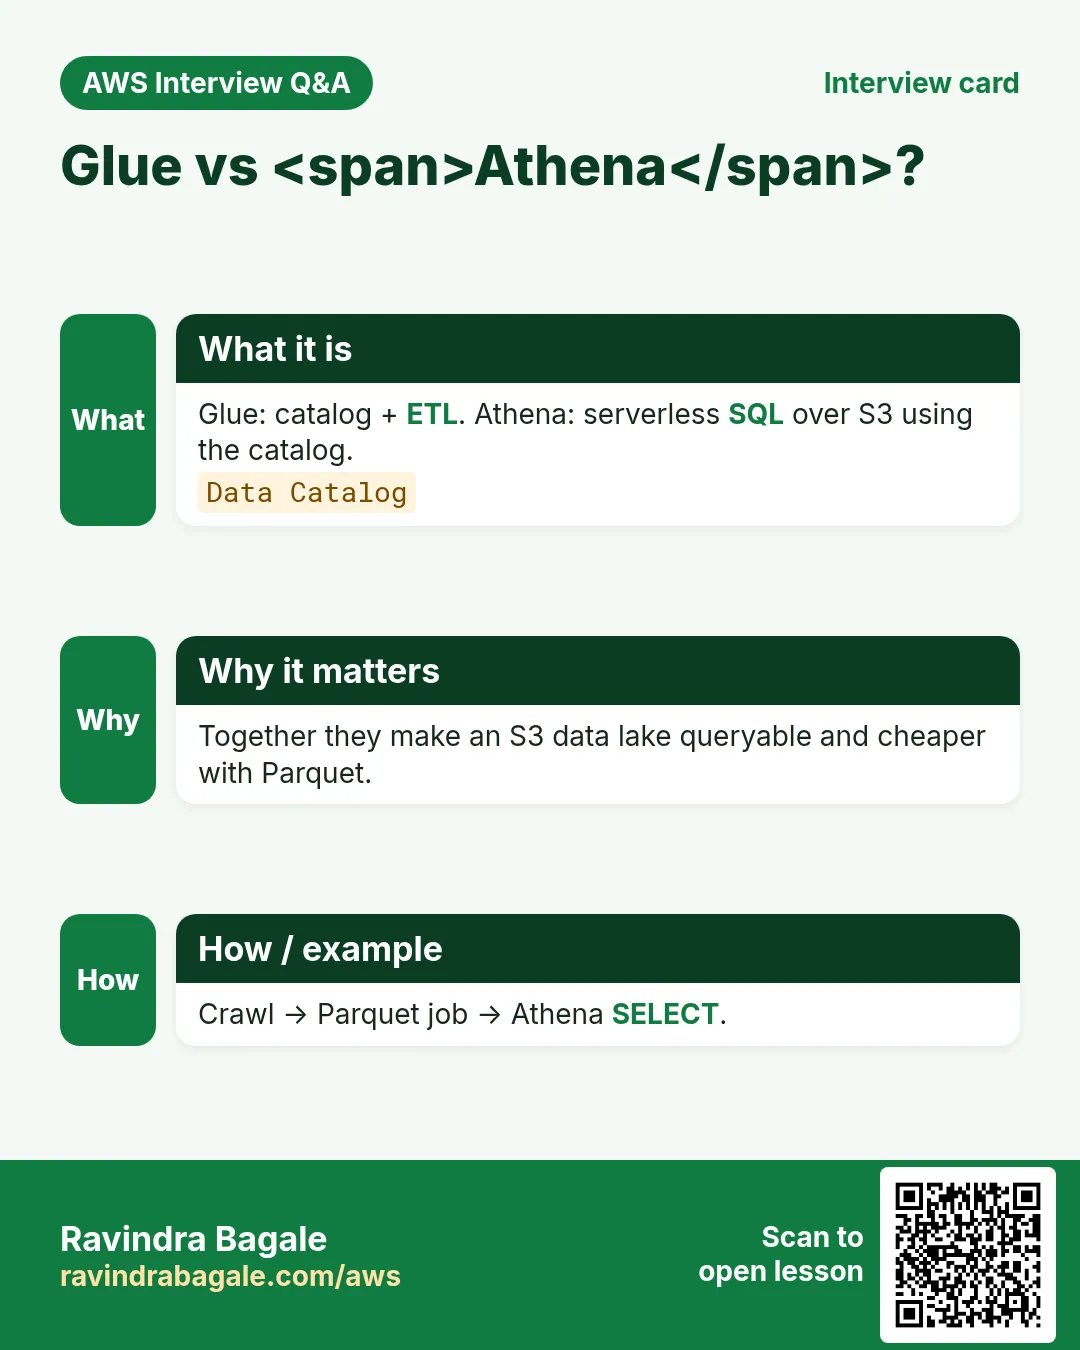
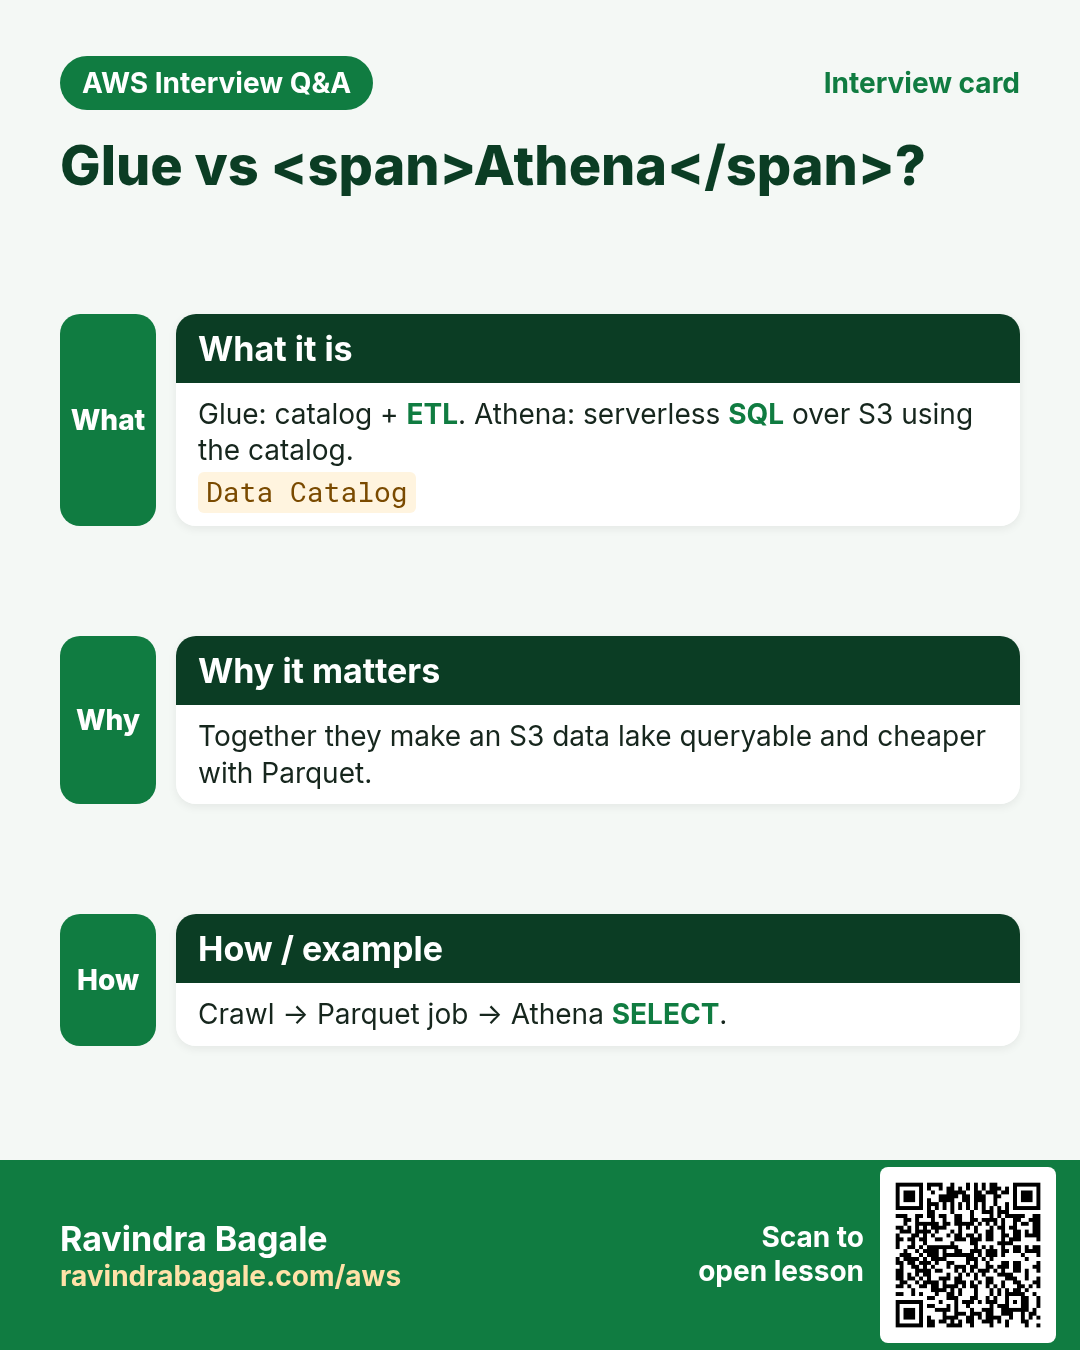
More cards: Ravi Sir's Cards.
Practice Tasks
Shivneri Schools is a education business in Junnar. Kavita Shinde looks after its IT and cloud work. They count money in INR and run their AWS resources in the ap-south-1 Region. In the tasks below you do real jobs for them using what this lesson teaches. All names, account IDs, IP addresses and numbers are made up for practice.
0 / 16
Easy List Glue databases
Why: Catalog inventory.
What to do: List Glue databases.
- Read the task and decide which AWS service it is about.
- Write aws, then the service name, then the operation (the action word).
- Add each needed flag (--name) followed by its value from the task.
- Flags can be in any order. Click Check answer.
Easy Get tables
Why: See lake tables.
What to do: Get tables in database shivnerischool_lake.
- Read the task and decide which AWS service it is about.
- Write aws, then the service name, then the operation (the action word).
- Add each needed flag (--name) followed by its value from the task.
- Flags can be in any order. Click Check answer.
Easy List workgroups
Why: Cost controls.
What to do: List Athena workgroups.
- Read the task and decide which AWS service it is about.
- Write aws, then the service name, then the operation (the action word).
- Add each needed flag (--name) followed by its value from the task.
- Flags can be in any order. Click Check answer.
Easy Athena bills by scan — 1
Why: Bytes scanned.
What to do: Enter 1 if Athena primarily bills by data scanned.
- Write down the numbers the task gives you.
- Work it out step by step on paper.
- Type only the final answer in the box.
- Click Check answer.
Easy Prefer Parquet — 1
Why: Columnar.
What to do: Enter 1 if Parquet is preferred over giant CSV for Athena.
- Write down the numbers the task gives you.
- Work it out step by step on paper.
- Type only the final answer in the box.
- Click Check answer.
Easy Public lake bad — 0
Why: Block public.
What to do: Is a public S3 data lake OK? Enter 0 for no.
- Write down the numbers the task gives you.
- Work it out step by step on paper.
- Type only the final answer in the box.
- Click Check answer.
Medium Get table
Why: Schema check.
What to do: Get table sales in shivnerischool_lake.
- Read the task and decide which AWS service it is about.
- Write aws, then the service name, then the operation (the action word).
- Add each needed flag (--name) followed by its value from the task.
- Flags can be in any order. Click Check answer.
Medium Get crawler
Why: Infer jobs.
What to do: Get crawler shivnerischool-sales.
- Read the task and decide which AWS service it is about.
- Write aws, then the service name, then the operation (the action word).
- Add each needed flag (--name) followed by its value from the task.
- Flags can be in any order. Click Check answer.
Medium Get query execution
Why: Check state/scanned.
What to do: Get query execution qid-123.
- Read the task and decide which AWS service it is about.
- Write aws, then the service name, then the operation (the action word).
- Add each needed flag (--name) followed by its value from the task.
- Flags can be in any order. Click Check answer.
Medium Athena results put
Why: Result bucket write.
What to do: Allow s3:PutObject on arn:aws:s3:::shivnerischool-ath-results/*.
- Start with { "Version": "2012-10-17", "Statement": [ ... ] }.
- In each statement write Effect, Action and Resource.
- Give only what the task needs (least privilege).
- Use double quotes and commas correctly. Click Check answer.
Medium Partition JSON
Why: Cost feature.
What to do: JSON date 2026-10-27.
- Start from the top-level keys the task names.
- Indent child keys with 2 spaces (no tabs).
- Fill in each property with the value from the task.
- Click Check answer. Key order does not matter.
Medium Workgroup limit GB sample
Why: Cap surprise bills.
What to do: Sample workgroup scan limit in GB for labs (enter 1)?
- Write down the numbers the task gives you.
- Work it out step by step on paper.
- Type only the final answer in the box.
- Click Check answer.
Hard Start crawler
Why: Refresh catalog.
What to do: Start crawler shivnerischool-sales.
- Read the task and decide which AWS service it is about.
- Write aws, then the service name, then the operation (the action word).
- Add each needed flag (--name) followed by its value from the task.
- Flags can be in any order. Click Check answer.
Hard Start query
Why: SQL on S3.
What to do: Start query execution with string SELECT 1 and workgroup primary.
- Read the task and decide which AWS service it is about.
- Write aws, then the service name, then the operation (the action word).
- Add each needed flag (--name) followed by its value from the task.
- Flags can be in any order. Click Check answer.
Hard Glue read lake bucket
Why: ETL needs GetObject.
What to do: Allow s3:GetObject on arn:aws:s3:::shivnerischool-lake/*.
- Start with { "Version": "2012-10-17", "Statement": [ ... ] }.
- In each statement write Effect, Action and Resource.
- Give only what the task needs (least privilege).
- Use double quotes and commas correctly. Click Check answer.
Hard Query meta JSON
Why: Always filter partitions.
What to do: JSON sql SELECT store_id FROM sales WHERE date = 2026-10-27.
- Start from the top-level keys the task names.
- Indent child keys with 2 spaces (no tabs).
- Fill in each property with the value from the task.
- Click Check answer. Key order does not matter.