Ravi Sir's Cards › AWS
Glue + Athena
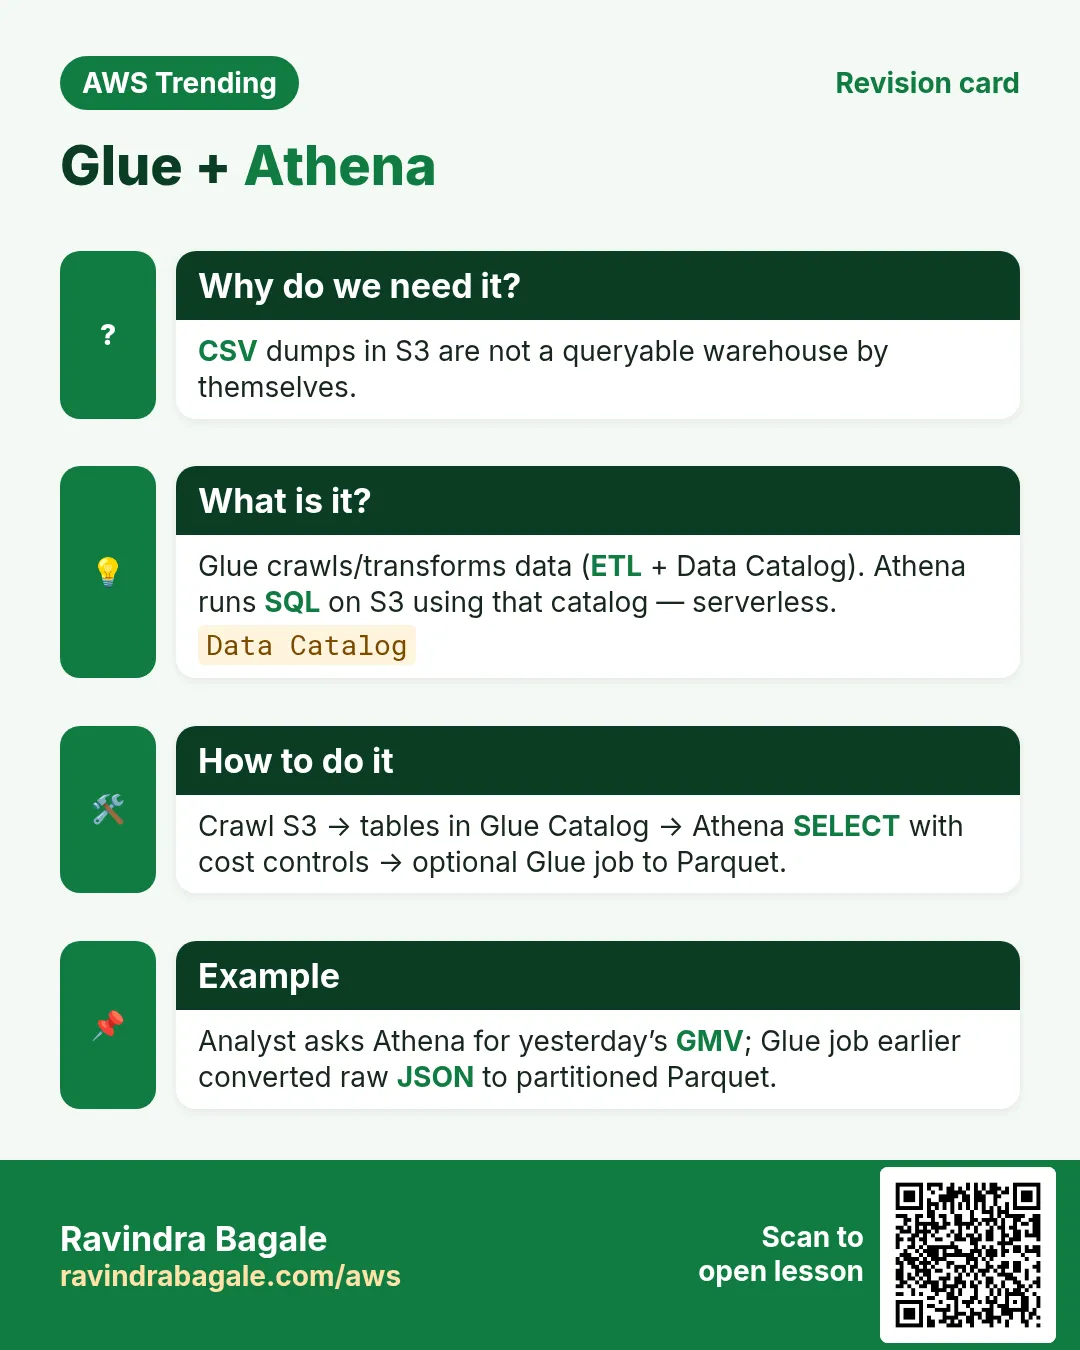
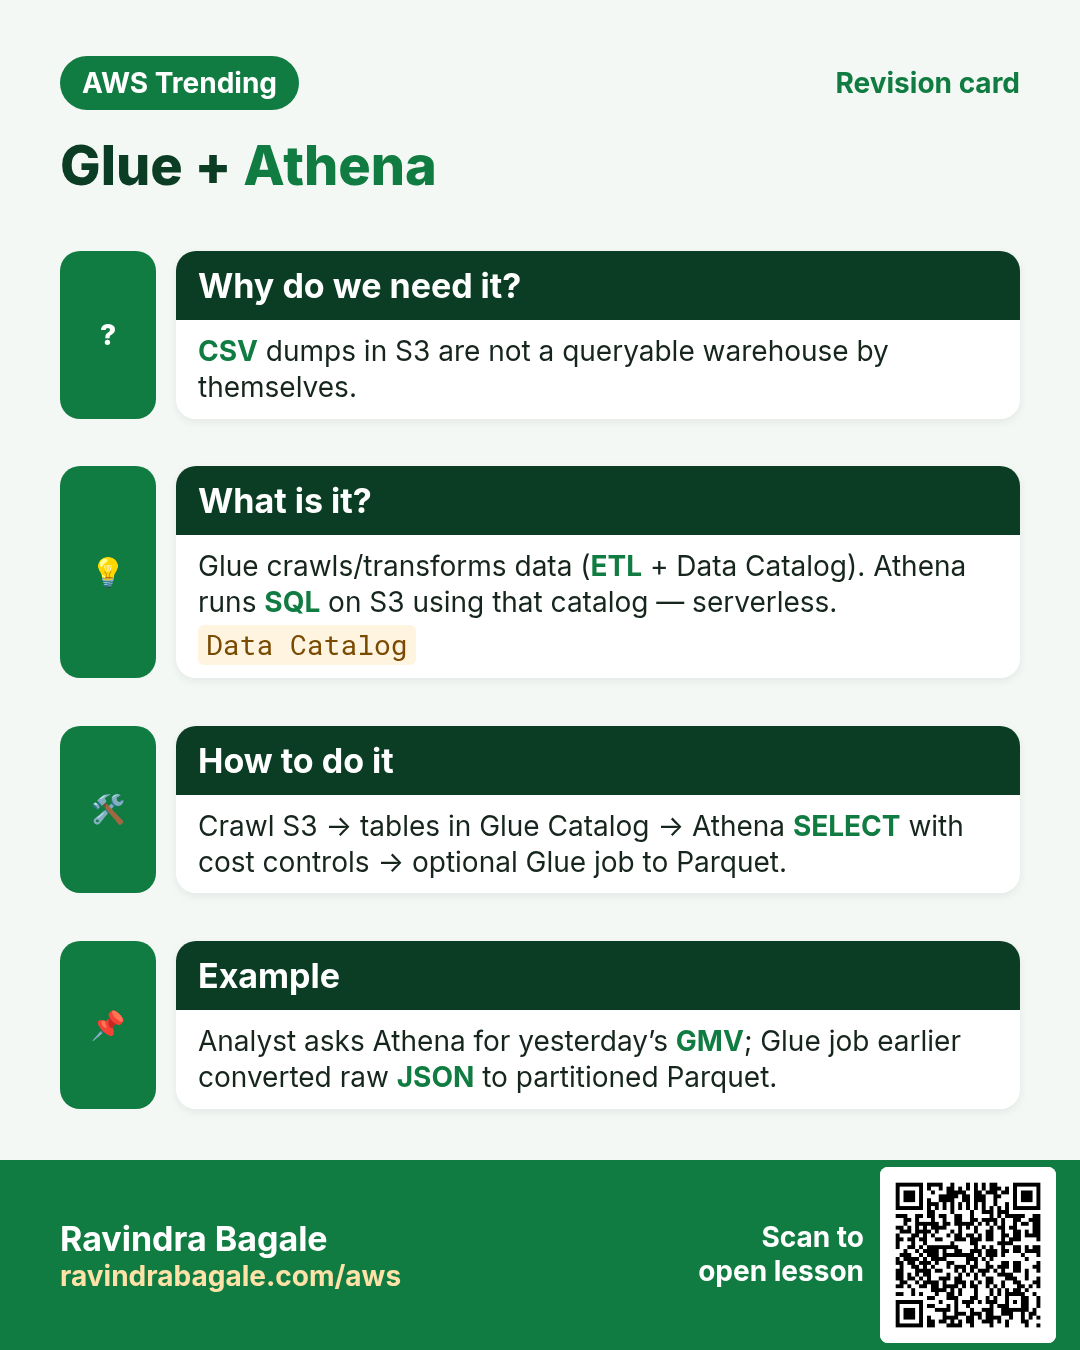
This revision card explains Glue + Athena. It starts from the need that CSV dumps in S3 are not a queryable warehouse by themselves. It describes glue crawls/transforms data (ETL + Data Catalog). Athena runs SQL on S3 using that catalog — serverless. The how-to section notes crawl S3 , then tables in Glue Catalog , then Athena SELECT with cost controls , then optional Glue job to Parquet. An example on the card is analyst asks Athena for yesterday’s GMV; Glue job earlier converted raw JSON to partitioned Parquet.
Read card text
What this card says
Why do we need it?
CSV dumps in S3 are not a queryable warehouse by themselves.
What is it?
Glue crawls/transforms data (ETL + Data Catalog). Athena runs SQL on S3 using that catalog — serverless.
Data Catalog
How to do it
Crawl S3 → tables in Glue Catalog → Athena SELECT with cost controls → optional Glue job to Parquet.
Example
Analyst asks Athena for yesterday’s GMV; Glue job earlier converted raw JSON to partitioned Parquet.