Ravi Sir's Cards › AWS
Glue ETL jobs
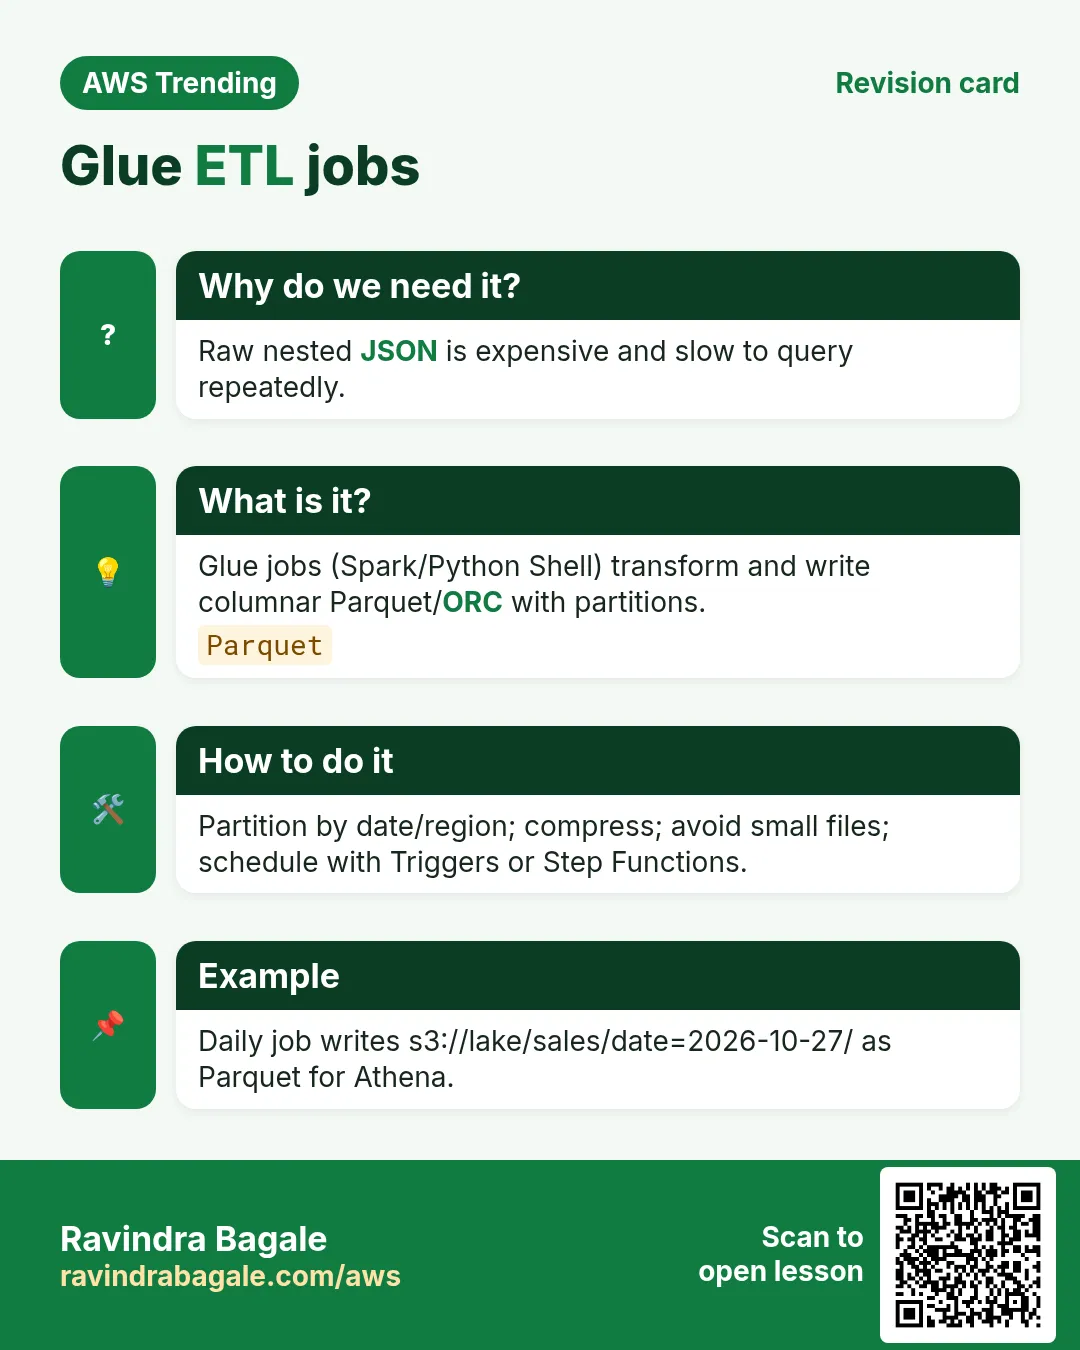
This revision card explains Glue ETL jobs. It starts from the need that raw nested JSON is expensive and slow to query repeatedly. It describes glue jobs (Spark/Python Shell) transform and write columnar Parquet/ORC with partitions. The how-to section notes partition by date/region; compress; avoid small files; schedule with Triggers or Step Functions. An example on the card is daily job writes s3://lake/sales/date=2026-10-27/ as Parquet for Athena.
Read card text
What this card says
Why do we need it?
Raw nested JSON is expensive and slow to query repeatedly.
What is it?
Glue jobs (Spark/Python Shell) transform and write columnar Parquet/ORC with partitions.
Parquet
How to do it
Partition by date/region; compress; avoid small files; schedule with Triggers or Step Functions.
Example
Daily job writes s3://lake/sales/date=2026-10-27/ as Parquet for Athena.